Embedding model - Reads each changed step and groups the ones that changed alike.
Replay testing for AI agents
Test your next prompt change on last week’s real conversations
Tapeback is a testing tool for AI agents. Before a prompt, model or tool change ships, it replays a sample of last week’s real conversations against it, and two models group the steps whose meaning changed, for a person to mark.
Replays run on traffic you already recorded. Nothing is sent to your users.
- 89%of teams in LangChain’s 2025 agent survey have observability
- 52.4%run offline evaluations, same survey
- 7 daysof your own real conversations, sampled for each replay
$npx tapeback init
#a week later, a pull request edits prompts/refund.md
$npx tapeback replay --change prompts/refund.md --days 7
The refund fix, replayed
Tuesday’s refund fix, run against last week before it shipped
I shipped a refund-prompt fix on a Tuesday. It passed every saved case. The agent stopped asking for an order number and answered from the wrong order for two days before anyone saw it. These steps replay that change against the week before, in an example workspace.
- 01recordOne command wraps your agent, and every conversation becomes a tape.
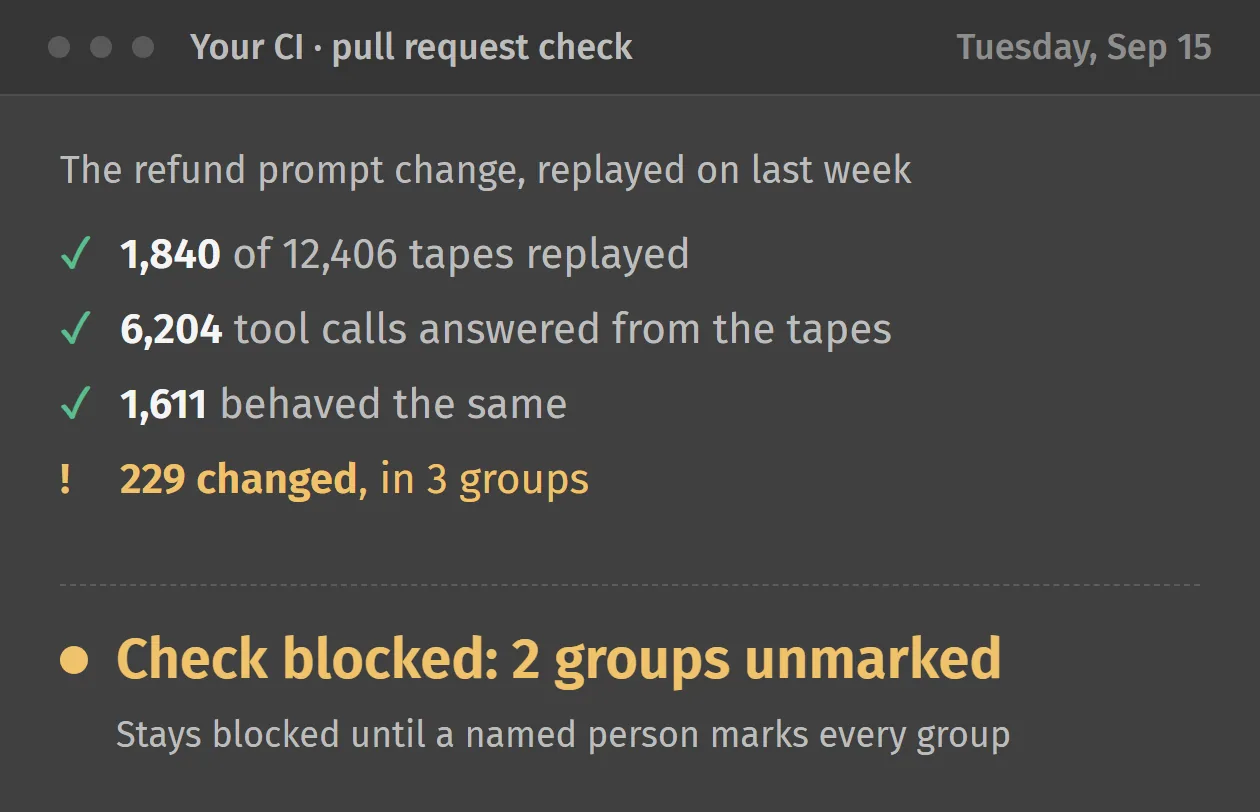
- 02sampleThe refund prompt changes. 1,840 of the week’s 12,406 tapes are drawn.
- 03replayThe changed agent gets each recorded history and writes the next step only.
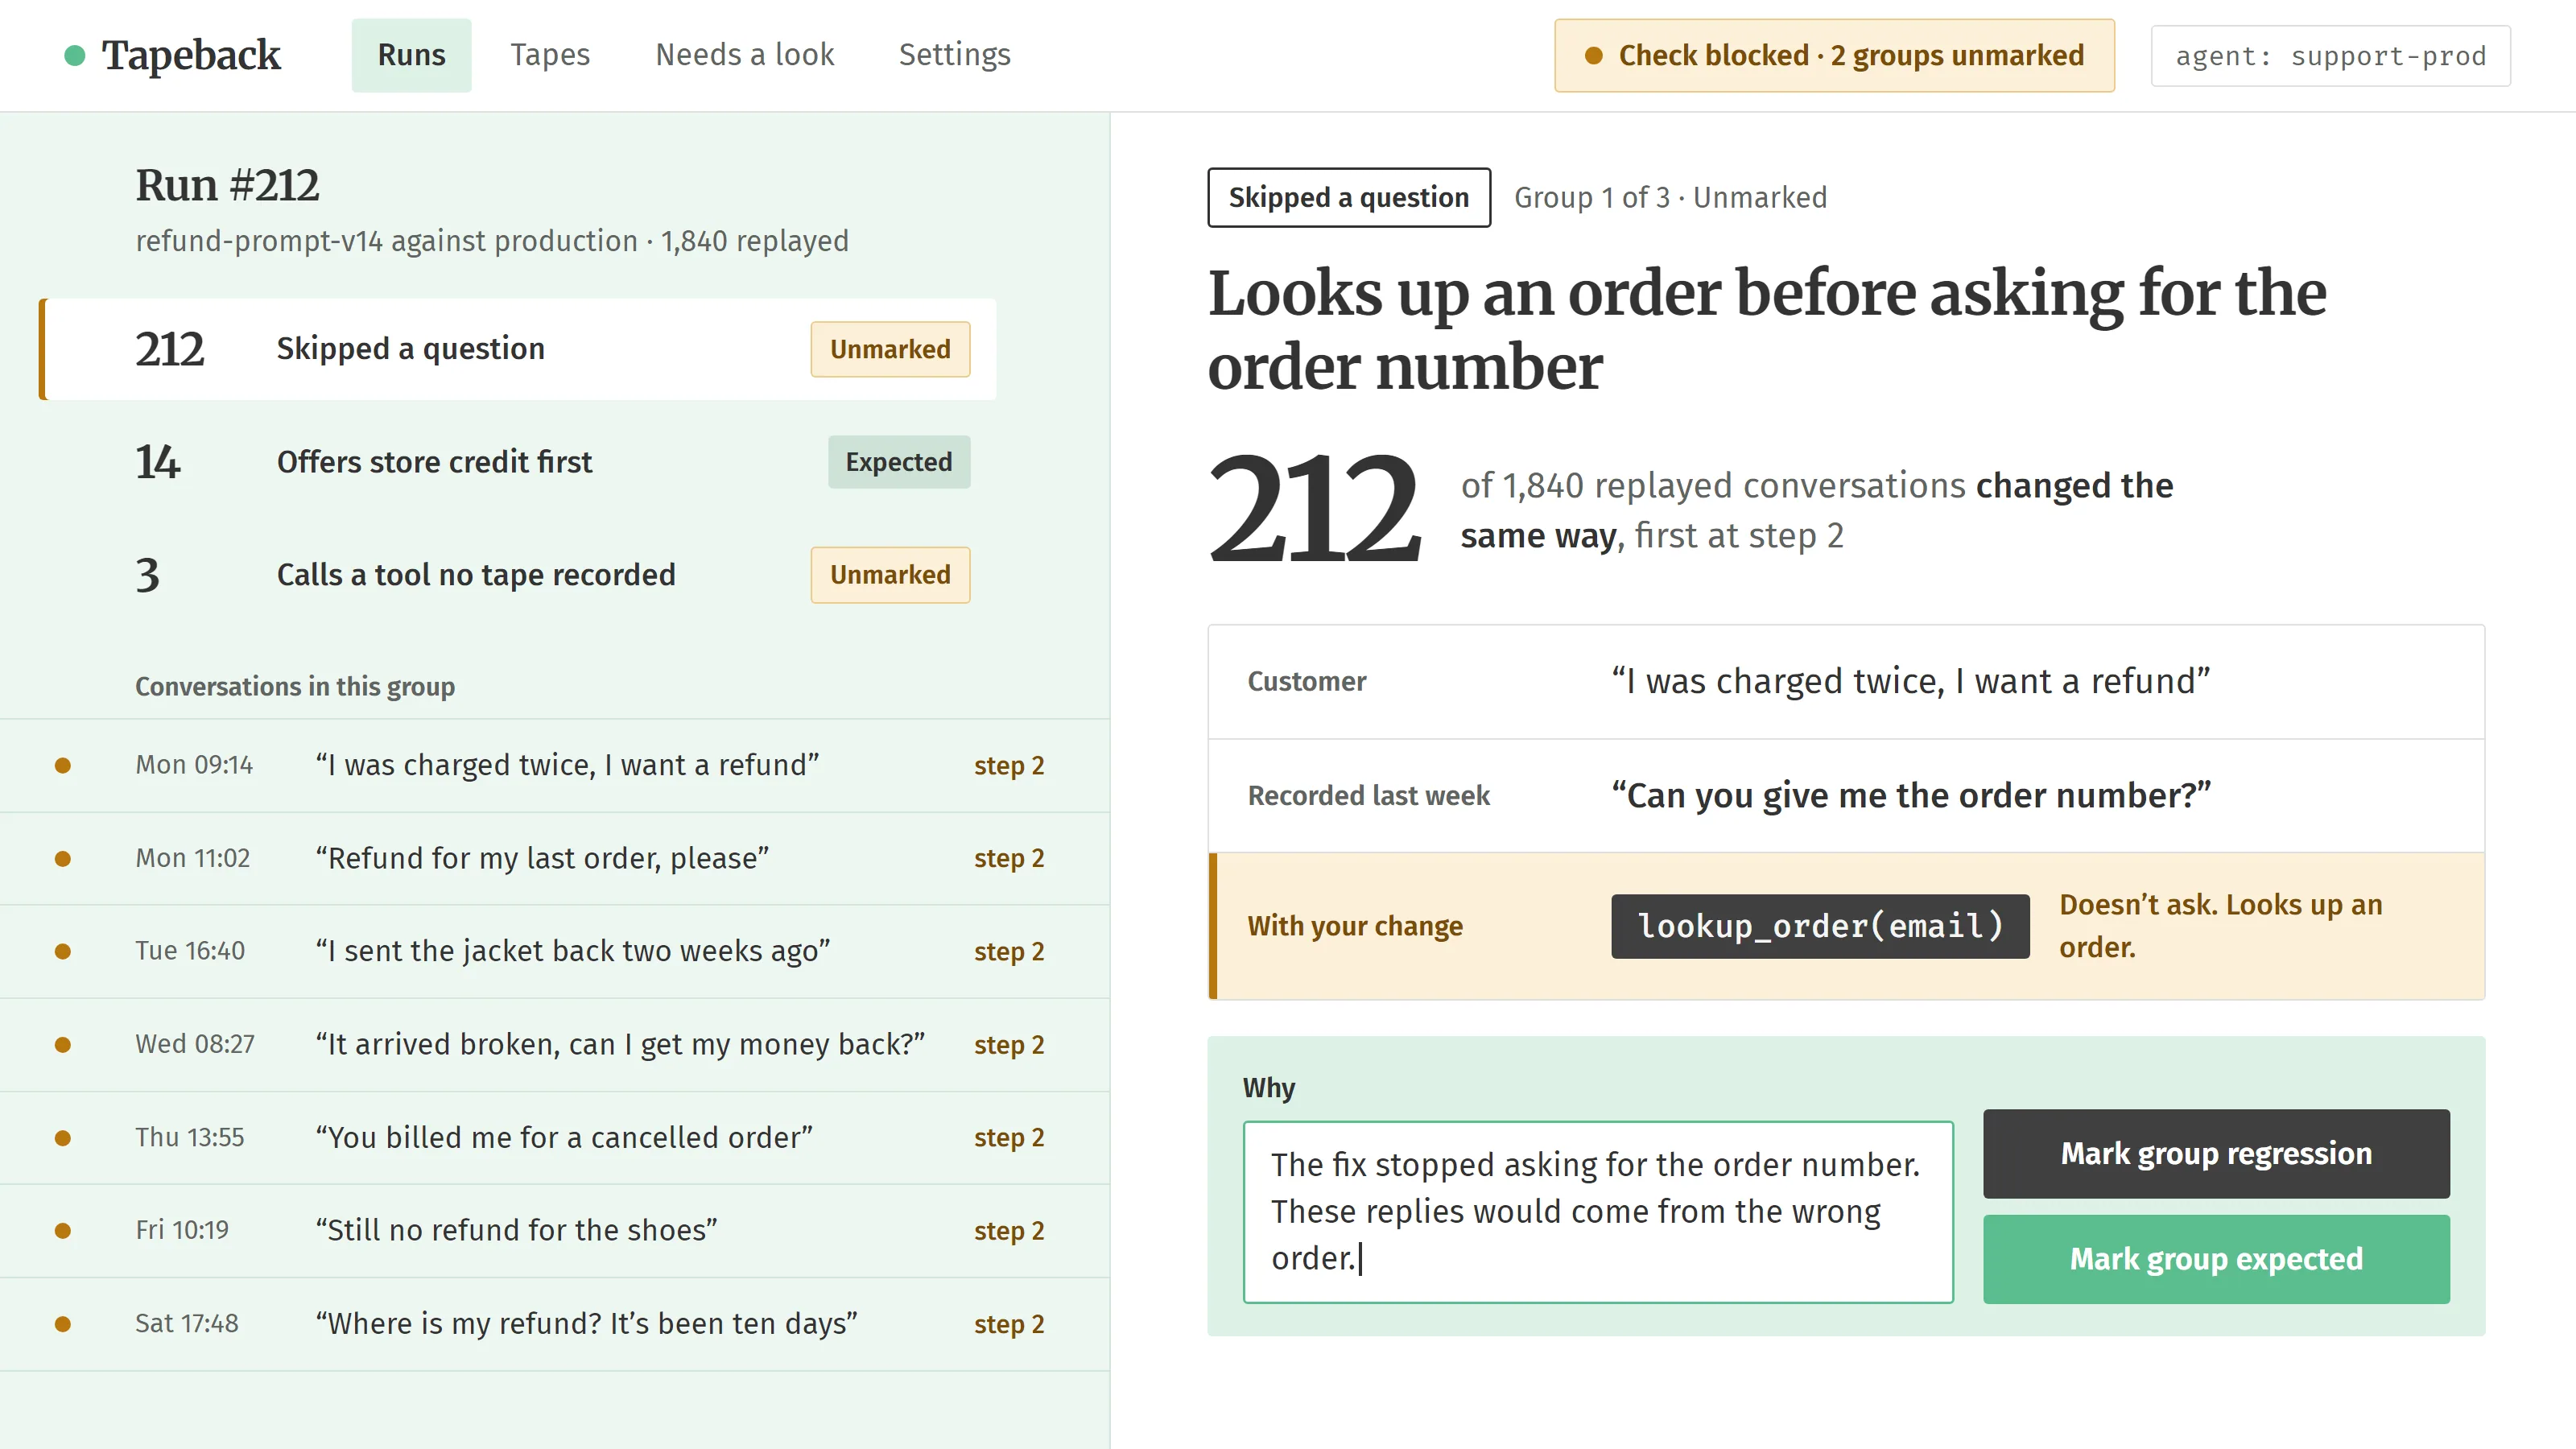
- 04group229 steps changed, in three groups. 212 skip the order-number question.
- 05markThe pull request stays blocked until a named person marks every group, and writes why.
A replay, start to finish
The week’s tapes, the grouped report, and the one step that changed
Same example run: a refund-prompt change against 1,840 recorded support conversations.
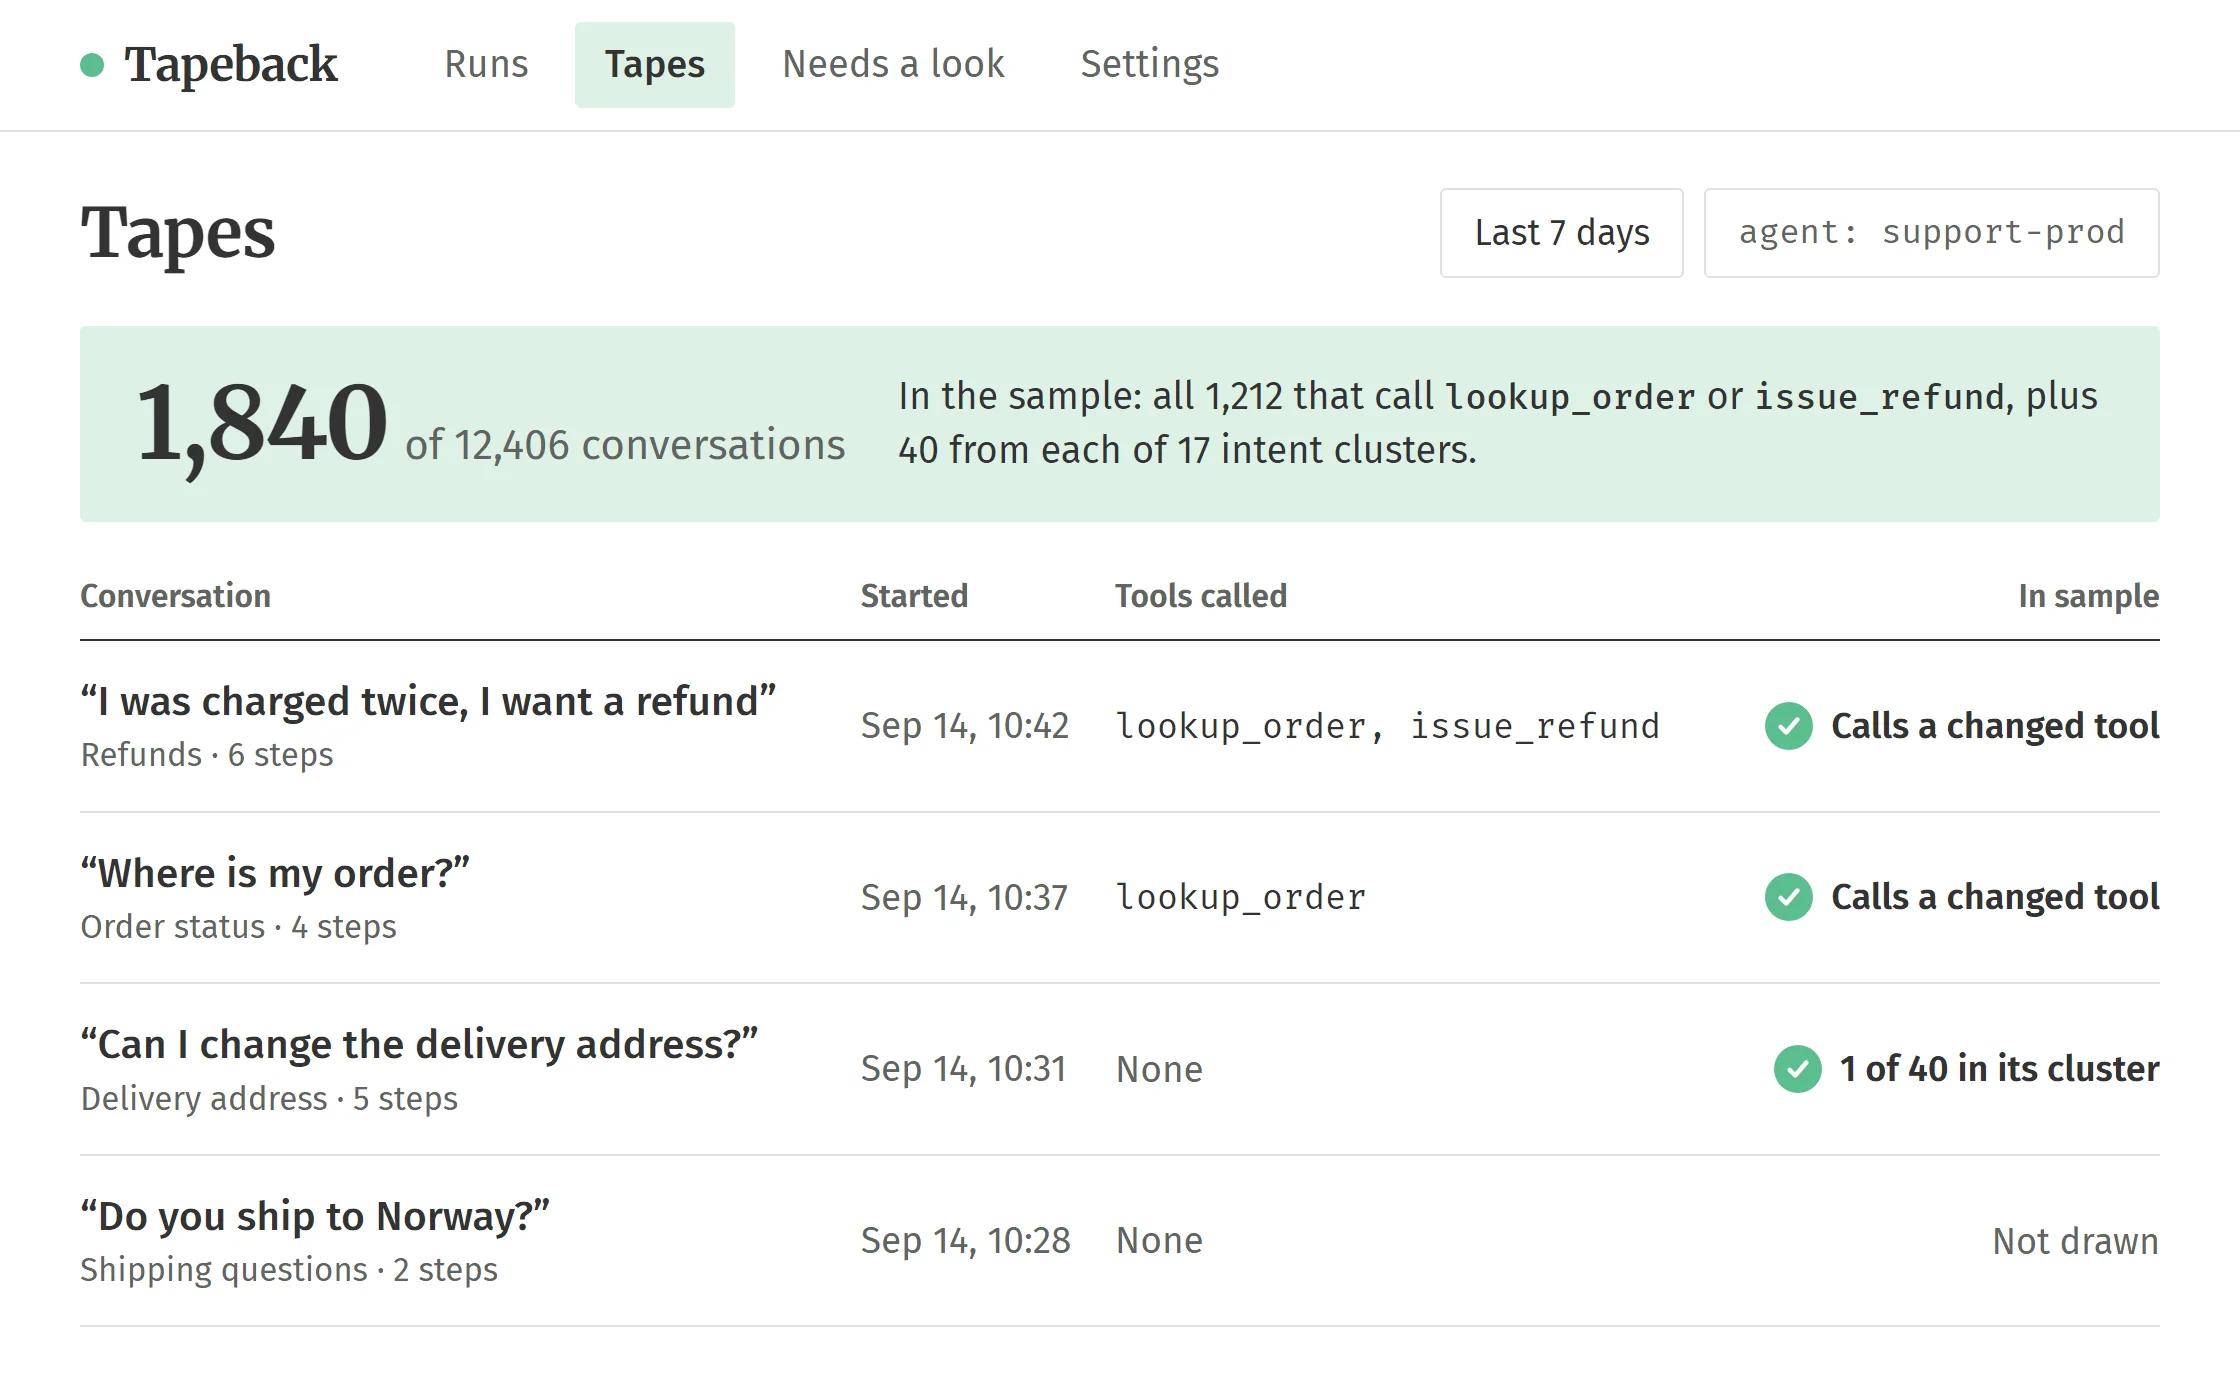
Tapes: Last week’s conversations, and the 1,840 drawn into the sample.
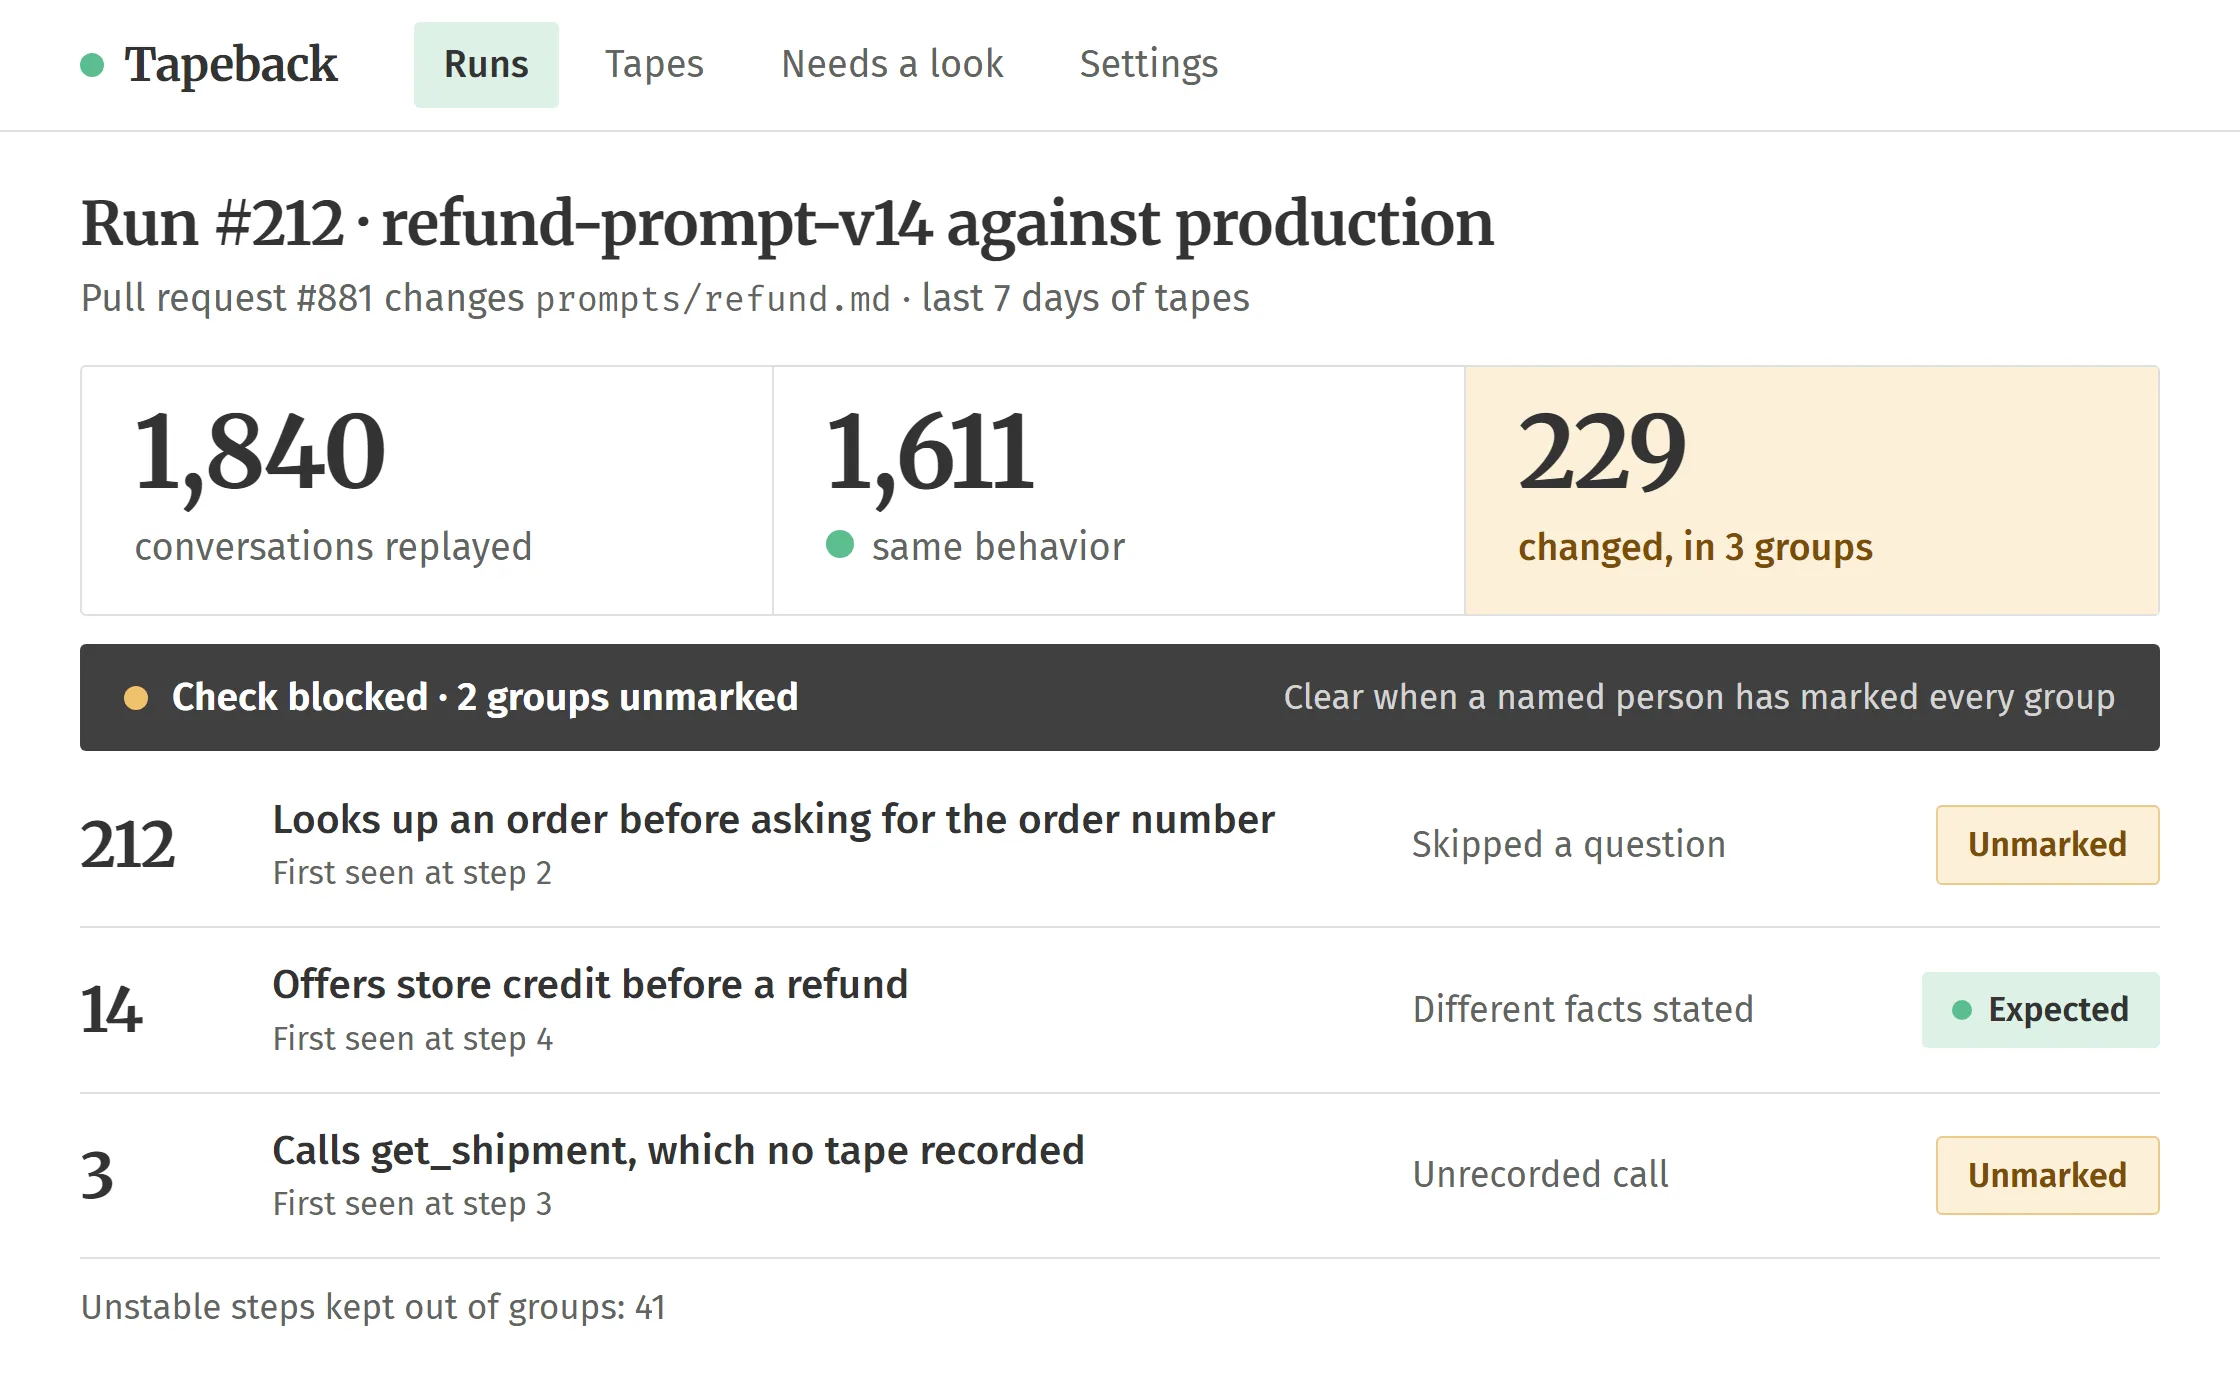
Run report: 229 changed steps in three groups, two unmarked, check blocked.
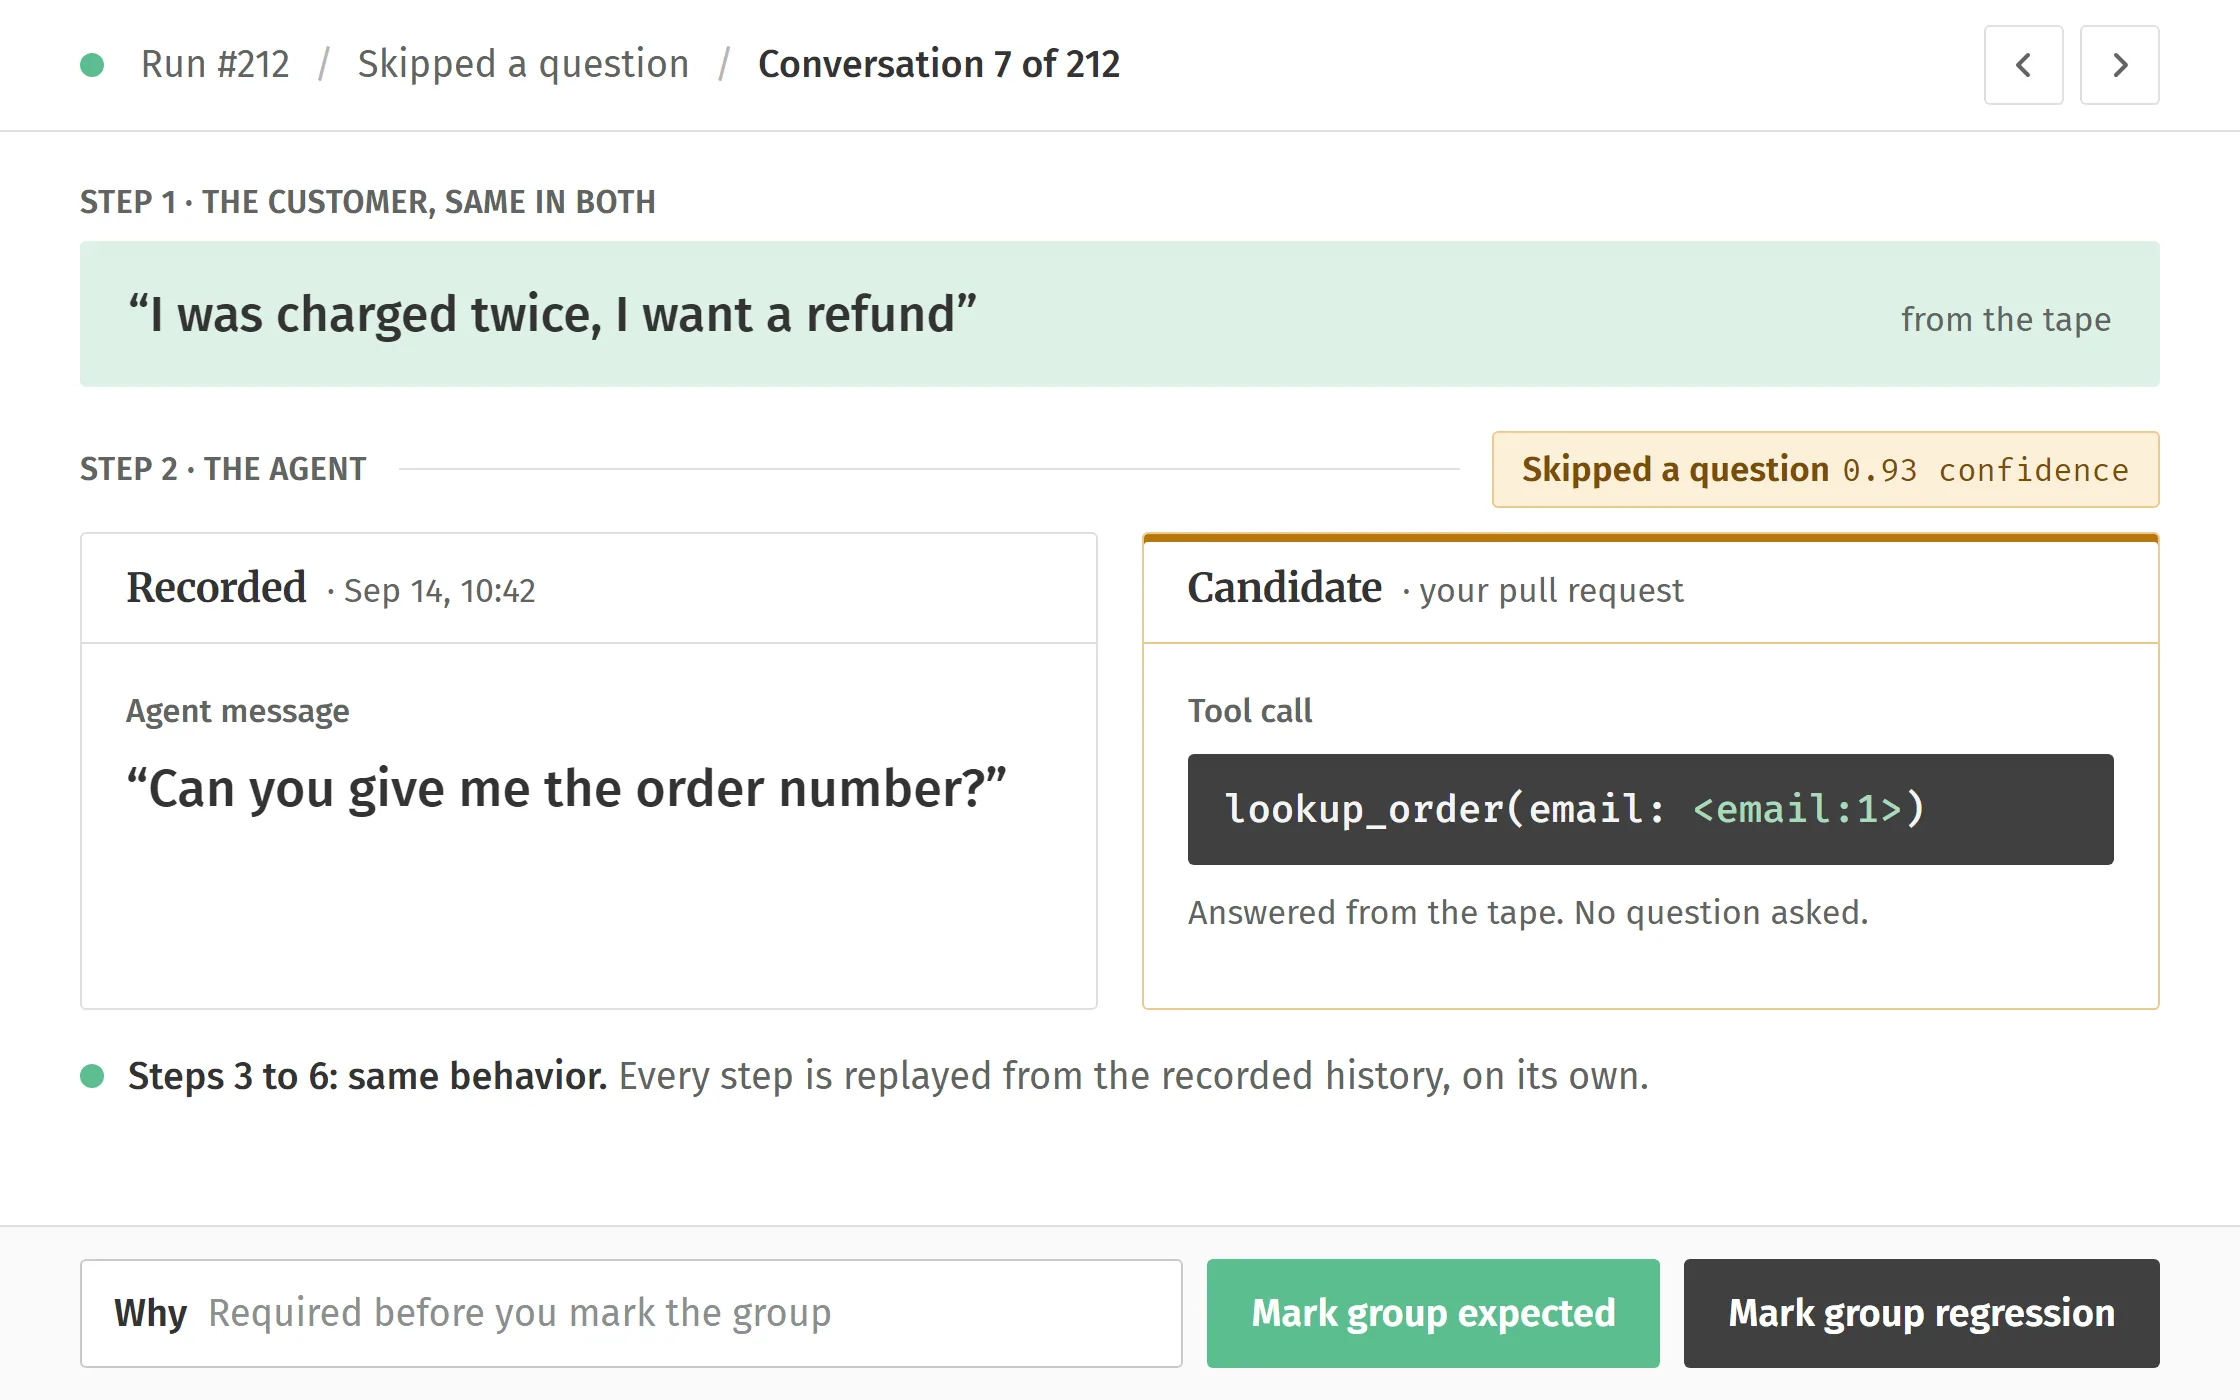
Step diff: The recording asks for an order number. The candidate doesn’t.
What sorts the changed steps
Rules compare structure. Two models read what the words now mean.
Their labels sort the report and never clear a change. Only a named person’s mark unblocks the pull request.
Pair classifier - Sets the recorded step beside your changed agent’s step and returns one of six labels, with a confidence.
Under 0.80 - No label is shown, and the step waits in Needs a look for an engineer to label by hand.
Training - Every mark leaves a labeled pair. Only pairs from opted-in workspaces may train the classifier, never tapes.
Why nothing alerted
A wrong answer and a right one return the same status code.
Nothing alerted, because nothing was broken except the answer.
—Tapebackon what a status code can’t tell you
A decision I’d defend
The check has no pass rate. A person reads the groups and signs them.
A prompt change is supposed to change behavior. So a percentage of changed steps can’t tell a fix from a break.
In the refund run, the fix and the missing question arrive together. Grouping turns 229 changed steps into three groups. A person can read three.
Every agent change waits for a human, including at six on a Friday, and there’s no single number for a dashboard.
- Tool calls are answered from the tape. A brand-new tool stops the replay there.
- No simulated user, so a break two turns later stays invisible.
- Every mark keeps a name and a reason, at a stable URL.
Once the new agent says something different, the real user’s next message no longer answers it.
A model playing your customer is an invented customer.
—Tapebackon why no replay simulates a user
Plugs into your stack
It wraps the framework your agent already runs on
The check runs in GitHub Actions, and a run summary posts to Slack.
npx tapeback import --days 7
- Ve
Vercel AI SDK
The recorder wraps your agent’s entry point.
- La
LangChain
Same wrapper. Tool arguments and results stay in order.
- Op
OpenAI Agents SDK
On OpenAI or Azure OpenAI, init adds the recorder and writes tapeback.config.ts.
- Cl
Claude Agent SDK
One tape per conversation, tool calls included.
- Op
OpenTelemetry
Any trace carrying full message and tool bodies.
- La
Langfuse and LangSmith
Import last week’s traces. Sampled ones are skipped.
Pricing
Team is $240 a month. Raindrop Pro starts at $299, and you’ll still want it.
Bench
$0per month
One engineer checking one agent’s changes from a laptop.
- 1 agent, 1 seat
- 300 replayed conversations a month
- 7 days of tapes kept
- CLI replay and the web run report
- Recording and redaction rules, never metered
- At the cap, replays pause until the 1st; recording does not
TeamCheck on every PR
$240per month
A team that ships agent changes through pull requests and wants the check on every one.
- 3 agents, 10 seats
- 10,000 replayed conversations a month, then $0.01 each
- 30 days of tapes kept
- GitHub check that blocks on unmarked groups
- Import from Langfuse, LangSmith or OpenTelemetry, never charged
- Run summary posted to a Slack channel
- Weekly baseline run and same-commit re-runs, not counted
Org
$900per month
Several agents, a security review to pass, and a record of who marked what.
- Unlimited agents, 40 seats
- 60,000 replayed conversations a month, then $0.008 each
- 90 days of tapes kept
- SSO / SAML included
- Audit log of every mark, rule change and export
- Signed data processing agreement and sub-processor list
- Email support answered by the next business day
Get an API key
- Bench stays free. No end date, no payment details.
- Team runs free for 30 days. Billing details come on day 30.
- Cancel in Settings. Tapes and runs export as JSONL for 30 days after.
- A workspace keeps the price it started on for 24 months.
What it does not do
Tapeback’s work ends when the pull request merges
Keep Raindrop for live traffic. Its pre-release replay, Simulations, is in research preview, and the stretch before release is where I work.
Replay last week before you ship this week
Your name and a work email get you a workspace key. If your traces already sit in Langfuse or LangSmith, last week’s tapes are in your workspace the same afternoon.
We reply within one business day.
- ✓ Adapters today: Vercel AI SDK, LangChain, OpenAI Agents SDK, Claude Agent SDK
- ✓ Nothing uploads until you’ve saved a redaction rule
- ✓ The replay spends your model tokens, under your key